

Column: Sparse Modeling
137
following equation:
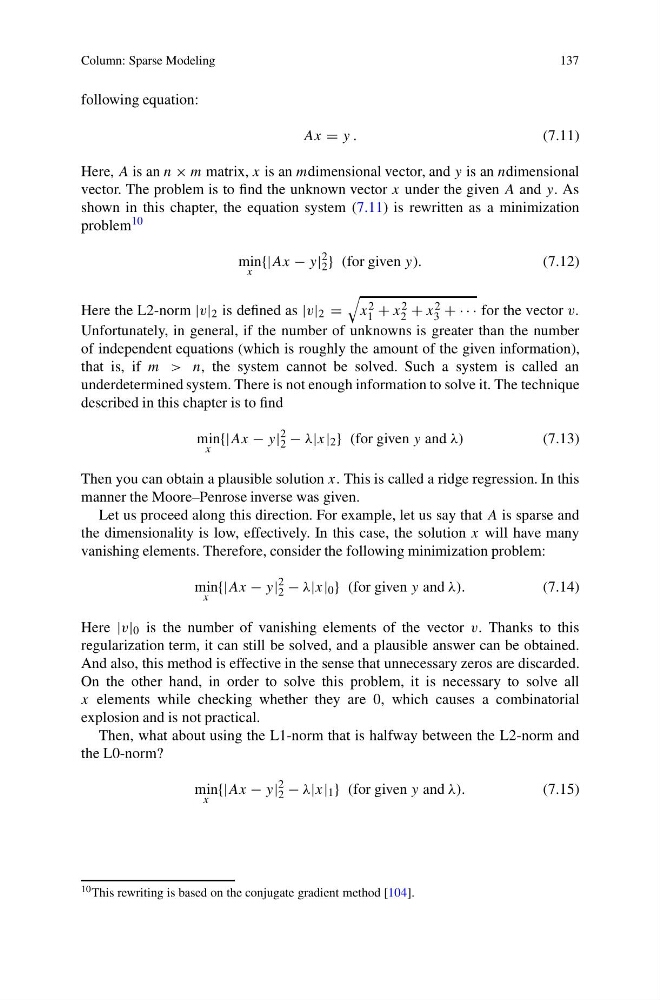
Ax = y .
(7.11)
Here, A is an n × m matrix, x is an mdimensional vector, and y is an ndimensional
vector. The problem is to find the unknown vector x under the given A and y. As
shown in this chapter, the equation system (7.11) is rewritten as a minimization
problem 10
min
x
{|Ax − y|
2
2 } (for given y).
(7.12)
Here the L2-norm |v| 2 is defined as |v| 2 =
x 2
1 + x 2
2 + x 2
3 + · · · for the vector v.
Unfortunately, in general, if the number of unknowns is greater than the number
of independent equations (which is roughly the amount of the given information),
that is, if m > n, the system cannot be solved. Such a system is called an
underdetermined system. There is not enough information to solve it. The technique
described in this chapter is to find
min
x
{|Ax − y|
2
2 − λ|x| 2 } (for given y and λ)
(7.13)
Then you can obtain a plausible solution x. This is called a ridge regression. In this
manner the Moore–Penrose inverse was given.
Let us proceed along this direction. For example, let us say that A is sparse and
the dimensionality is low, effectively. In this case, the solution x will have many
vanishing elements. Therefore, consider the following minimization problem:
min
x
{|Ax − y|
2
2 − λ|x| 0 } (for given y and λ).
(7.14)
Here |v| 0 is the number of vanishing elements of the vector v. Thanks to this
regularization term, it can still be solved, and a plausible answer can be obtained.
And also, this method is effective in the sense that unnecessary zeros are discarded.
On the other hand, in order to solve this problem, it is necessary to solve all
x elements while checking whether they are 0, which causes a combinatorial
explosion and is not practical.
Then, what about using the L1-norm that is halfway between the L2-norm and
the L0-norm?
min
x
{|Ax − y|
2
2 − λ|x| 1 } (for given y and λ).
(7.15)
10 This rewriting is based on the conjugate gradient method [104].