

3 Uncertainty Quantification in Lasso-Type Regularization Problems
85
methods, like MCMC, need to be employed. The posterior distribution is then
used for further inference. For instance, we can look at its mean, mode, or other
characteristics.
3.1.3 Linear Models
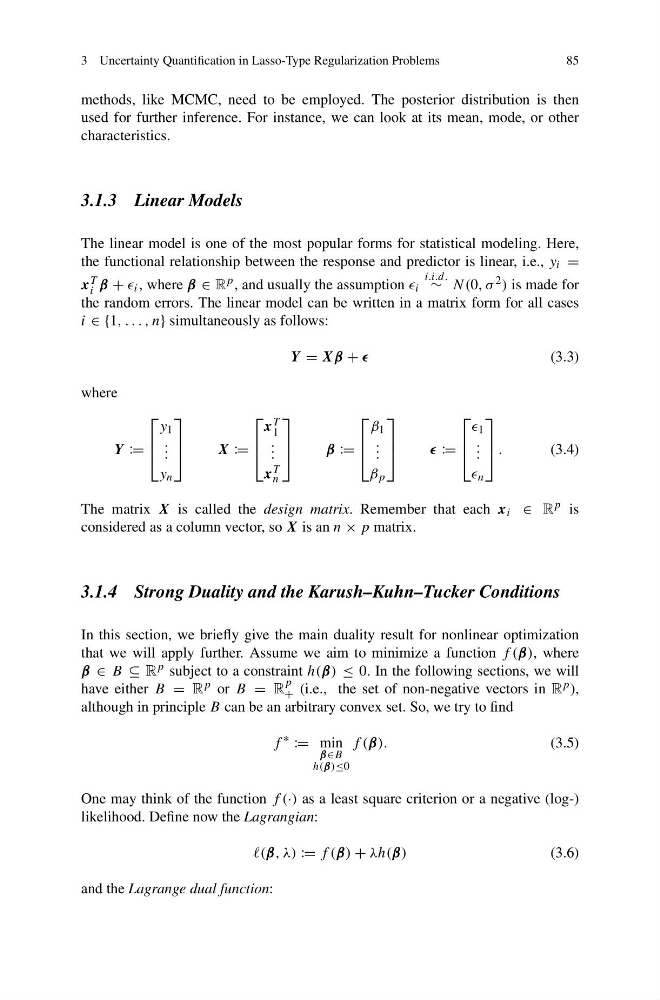
The linear model is one of the most popular forms for statistical modeling. Here,
the functional relationship between the response and predictor is linear, i.e., y i =
x T
i β + i , where β ∈ R p , and usually the assumption i
i.i.d.
∼ N(0, σ 2 ) is made for
the random errors. The linear model can be written in a matrix form for all cases
i ∈ {1, . . . , n} simultaneously as follows:
Y = Xβ +
(3.3)
where
Y :=
⎡
⎢
⎣
y 1
. . .
y n
⎤
⎥
⎦
X :=
⎡
⎢
⎣
x T
1
. . .
x T
n
⎤
⎥
⎦
β :=
⎡
⎢
⎣
β 1
. . .
β p
⎤
⎥
⎦
:=
⎡
⎢
⎣
1
. . .
n
⎤
⎥
⎦ .
(3.4)
The matrix X is called the design matrix. Remember that each x i ∈ R p is
considered as a column vector, so X is an n × p matrix.
3.1.4 Strong Duality and the Karush–Kuhn–Tucker Conditions
In this section, we briefly give the main duality result for nonlinear optimization
that we will apply further. Assume we aim to minimize a function f (β), where
β ∈ B ⊆ R p subject to a constraint h(β) ≤ 0. In the following sections, we will
have either B = R p or B = R
p
+ (i.e., the set of non-negative vectors in R p ),
although in principle B can be an arbitrary convex set. So, we try to find
f
∗
:= min
β∈B
h(β)≤0
f (β).
(3.5)
One may think of the function f (·) as a least square criterion or a negative (log-)
likelihood. Define now the Lagrangian:
(β, λ) := f (β) + λh(β)
(3.6)
and the Lagrange dual function: