

204
C. Greco and M. Vasile
p(y k , x k |y 1:k−1 ) = p(y k |x k , y 1:k−1 )p(x k |y 1:k−1 )
= p(y k |x k )p(x k |y 1:k−1 )
= N y k (H (t k )x k , R k )N x k (ˆ x
−
k , P
−
k )
= N x k ,y k
ˆ
x
−
k
H (t k )ˆ x
−
k
,
P
−
k
P
−
k H T
k
H k P
−
k H k P
−
k H T
k + R k
.
(6.60)
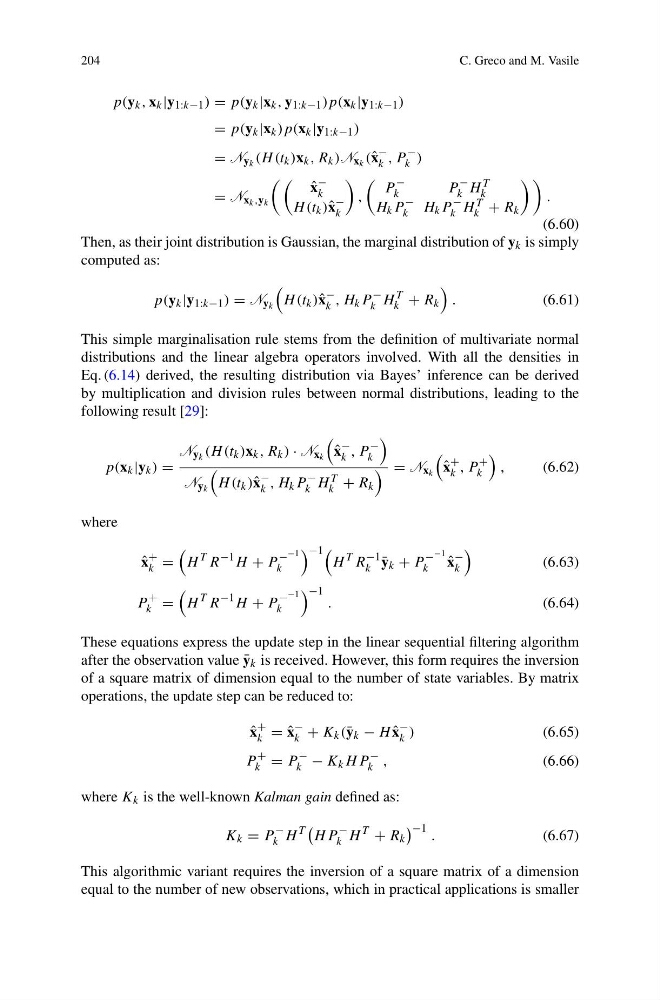
Then, as their joint distribution is Gaussian, the marginal distribution of y k is simply
computed as:
p(y k |y 1:k−1 ) = N y k
H (t k )ˆ x
−
k , H k P
−
k H
T
k + R k
.
(6.61)
This simple marginalisation rule stems from the definition of multivariate normal
distributions and the linear algebra operators involved. With all the densities in
Eq. (6.14) derived, the resulting distribution via Bayes’ inference can be derived
by multiplication and division rules between normal distributions, leading to the
following result [29]:
p(x k |y k ) =
N y k (H (t k )x k , R k ) · N x k
ˆ
x
−
k , P
−
k
N y k
H (t k )ˆ x
−
k , H k P
−
k H T
k + R k
= N x k
ˆ
x
+
k , P
+
k
,
(6.62)
where
ˆ
x
+
k =
H
T R
−1 H + P
− −1
k
−1
H
T R
−1
k ¯
y k + P
− −1
k
ˆ
x
−
k
(6.63)
P
+
k =
H
T R
−1 H + P
− −1
k
−1
.
(6.64)
These equations express the update step in the linear sequential filtering algorithm
after the observation value ¯
y k is received. However, this form requires the inversion
of a square matrix of dimension equal to the number of state variables. By matrix
operations, the update step can be reduced to:
ˆ
x
+
k = ˆ
x
−
k + K k (¯ y k − H ˆ
x
−
k )
(6.65)
P
+
k = P
−
k − K k H P
−
k ,
(6.66)
where K k is the well-known Kalman gain defined as:
K k = P
−
k H
T
H P
−
k H
T
+ R k
−1 .
(6.67)
This algorithmic variant requires the inversion of a square matrix of a dimension
equal to the number of new observations, which in practical applications is smaller