

3 CNN Model
ALexNet [2] is considered to be one of the most far-reaching models in the industry,
achieving a 15.4% success in the top five test error rate. It is much better than the
26.2% of the second place, indicating that CNN has a surprising advantage over other
methods. Its layout structure is relatively simple compared to some current architectures. It mainly includes five convolutional layers, dropout layer, maximum pooling
layer, and three fully connected layers. The data set uses the Imagenet data set, which
has a data set of 15 million high-resolution images with labels, with approximately
22,000 categories. The activation function uses the ReLu function, which is six times
faster than the activation function using tanh neurons. Excessive training sets make it
unsuitable for training on one GPU, and parallel computing on two GPUs can achieve
good results. The network has 60 million parameters, although there are many categories in our data set, these categories are not enough for so many parameters. In order
to reduce the overfitting of the network, the model uses data-enhanced technology, that
is, artificially expand the data set by image transformation, horizontal reflection, patch
extractions, etc. In addition, the model also uses the dropout technique to reduce
overfitting. Its approach is to set the output of each neuron to zero with a probability of
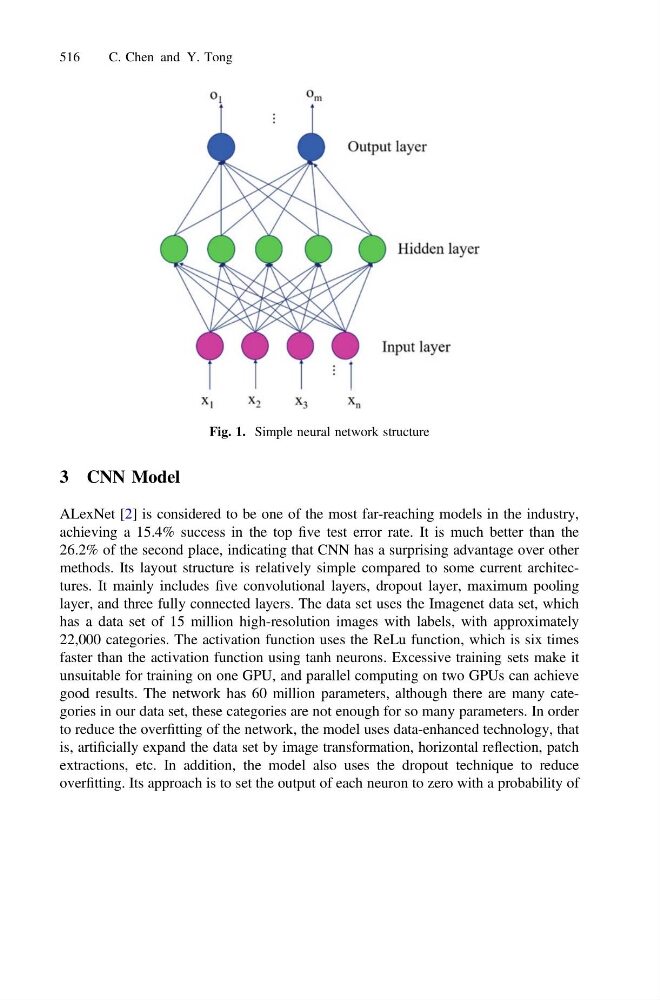
Fig. 1. Simple neural network structure
516
C. Chen and Y. Tong