

S ¼
Y
iA
B i Â
X
jpos
PR m
Y
iA
B i Â
X
nlevel
LE n
ð3:4Þ
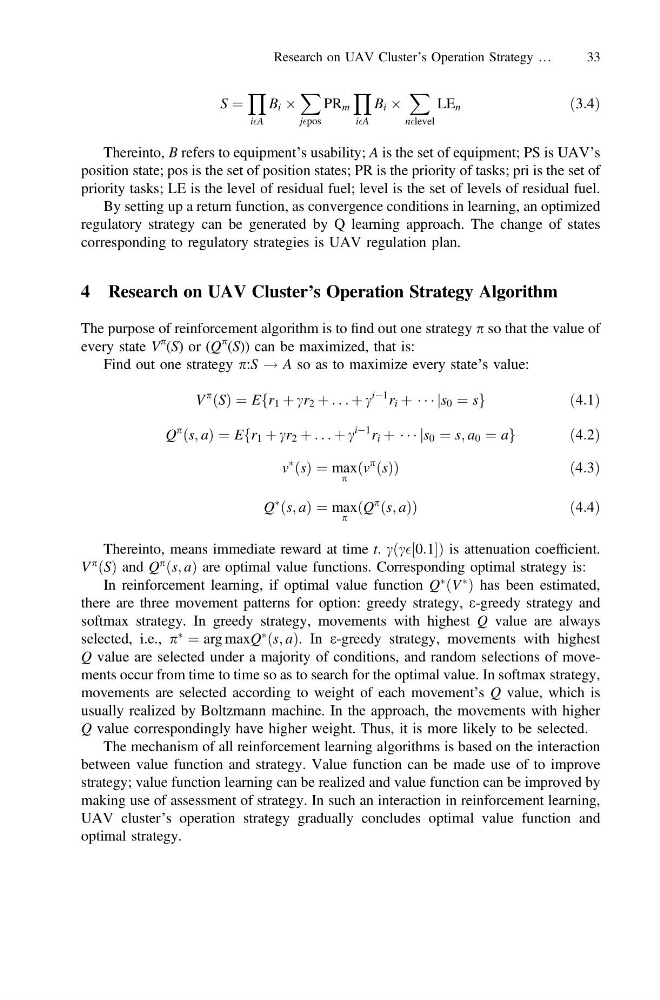
Thereinto, B refers to equipment’s usability; A is the set of equipment; PS is UAV’s
position state; pos is the set of position states; PR is the priority of tasks; pri is the set of
priority tasks; LE is the level of residual fuel; level is the set of levels of residual fuel.
By setting up a return function, as convergence conditions in learning, an optimized
regulatory strategy can be generated by Q learning approach. The change of states
corresponding to regulatory strategies is UAV regulation plan.
4 Research on UAV Cluster’s Operation Strategy Algorithm
The purpose of reinforcement algorithm is to find out one strategy p so that the value of
every state V
p (S) or (Q
p (S)) can be maximized, that is:
Find out one strategy p:S ! A so as to maximize every state’s value:
V
p S
ð Þ ¼ Efr 1 þ cr 2 þ . . . þ c
iÀ1 r i þ Á Á Á js 0 ¼ sg
ð 4:1Þ
Q
p s; a
ð Þ ¼ Efr 1 þ cr 2 þ . . . þ c
iÀ1 r i þ Á Á Á js 0 ¼ s; a 0 ¼ ag
ð 4:2Þ
v
à s
ð Þ ¼ max
p
v
p s
ð Þ
ð
Þ
ð4:3Þ
Q
à s; a
ð Þ ¼ max
p
Q
p s; a
ð Þ
ð
Þ
ð 4:4Þ
Thereinto, means immediate reward at time t. c c 0:1
½
ð
Þis attenuation coefficient.
V
p S
ð Þ and Q
p s; a
ð Þ are optimal value functions. Corresponding optimal strategy is:
In reinforcement learning, if optimal value function Q
à V
Ã
ð Þ has been estimated,
there are three movement patterns for option: greedy strategy, e-greedy strategy and
softmax strategy. In greedy strategy, movements with highest Q value are always
selected, i.e., p
Ã
¼ arg maxQ
à s; a
ð Þ. In e-greedy strategy, movements with highest
Q value are selected under a majority of conditions, and random selections of movements occur from time to time so as to search for the optimal value. In softmax strategy,
movements are selected according to weight of each movement’s Q value, which is
usually realized by Boltzmann machine. In the approach, the movements with higher
Q value correspondingly have higher weight. Thus, it is more likely to be selected.
The mechanism of all reinforcement learning algorithms is based on the interaction
between value function and strategy. Value function can be made use of to improve
strategy; value function learning can be realized and value function can be improved by
making use of assessment of strategy. In such an interaction in reinforcement learning,
UAV cluster’s operation strategy gradually concludes optimal value function and
optimal strategy.
Research on UAV Cluster’s Operation Strategy …
33
Y
iA
B i Â
X
jpos
PR m
Y
iA
B i Â
X
nlevel
LE n
ð3:4Þ
Thereinto, B refers to equipment’s usability; A is the set of equipment; PS is UAV’s
position state; pos is the set of position states; PR is the priority of tasks; pri is the set of
priority tasks; LE is the level of residual fuel; level is the set of levels of residual fuel.
By setting up a return function, as convergence conditions in learning, an optimized
regulatory strategy can be generated by Q learning approach. The change of states
corresponding to regulatory strategies is UAV regulation plan.
4 Research on UAV Cluster’s Operation Strategy Algorithm
The purpose of reinforcement algorithm is to find out one strategy p so that the value of
every state V
p (S) or (Q
p (S)) can be maximized, that is:
Find out one strategy p:S ! A so as to maximize every state’s value:
V
p S
ð Þ ¼ Efr 1 þ cr 2 þ . . . þ c
iÀ1 r i þ Á Á Á js 0 ¼ sg
ð 4:1Þ
Q
p s; a
ð Þ ¼ Efr 1 þ cr 2 þ . . . þ c
iÀ1 r i þ Á Á Á js 0 ¼ s; a 0 ¼ ag
ð 4:2Þ
v
à s
ð Þ ¼ max
p
v
p s
ð Þ
ð
Þ
ð4:3Þ
Q
à s; a
ð Þ ¼ max
p
Q
p s; a
ð Þ
ð
Þ
ð 4:4Þ
Thereinto, means immediate reward at time t. c c 0:1
½
ð
Þis attenuation coefficient.
V
p S
ð Þ and Q
p s; a
ð Þ are optimal value functions. Corresponding optimal strategy is:
In reinforcement learning, if optimal value function Q
à V
Ã
ð Þ has been estimated,
there are three movement patterns for option: greedy strategy, e-greedy strategy and
softmax strategy. In greedy strategy, movements with highest Q value are always
selected, i.e., p
Ã
¼ arg maxQ
à s; a
ð Þ. In e-greedy strategy, movements with highest
Q value are selected under a majority of conditions, and random selections of movements occur from time to time so as to search for the optimal value. In softmax strategy,
movements are selected according to weight of each movement’s Q value, which is
usually realized by Boltzmann machine. In the approach, the movements with higher
Q value correspondingly have higher weight. Thus, it is more likely to be selected.
The mechanism of all reinforcement learning algorithms is based on the interaction
between value function and strategy. Value function can be made use of to improve
strategy; value function learning can be realized and value function can be improved by
making use of assessment of strategy. In such an interaction in reinforcement learning,
UAV cluster’s operation strategy gradually concludes optimal value function and
optimal strategy.
Research on UAV Cluster’s Operation Strategy …
33