

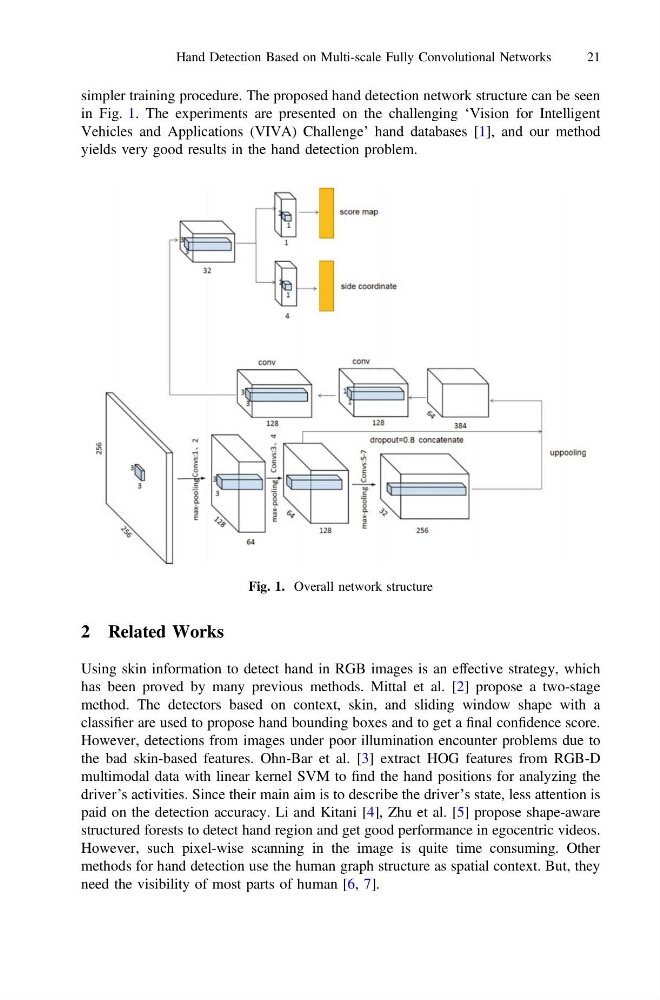
simpler training procedure. The proposed hand detection network structure can be seen
in Fig. 1. The experiments are presented on the challenging ‘Vision for Intelligent
Vehicles and Applications (VIVA) Challenge’ hand databases [1], and our method
yields very good results in the hand detection problem.
2 Related Works
Using skin information to detect hand in RGB images is an effective strategy, which
has been proved by many previous methods. Mittal et al. [2] propose a two-stage
method. The detectors based on context, skin, and sliding window shape with a
classifier are used to propose hand bounding boxes and to get a final confidence score.
However, detections from images under poor illumination encounter problems due to
the bad skin-based features. Ohn-Bar et al. [3] extract HOG features from RGB-D
multimodal data with linear kernel SVM to find the hand positions for analyzing the
driver’s activities. Since their main aim is to describe the driver’s state, less attention is
paid on the detection accuracy. Li and Kitani [4], Zhu et al. [5] propose shape-aware
structured forests to detect hand region and get good performance in egocentric videos.
However, such pixel-wise scanning in the image is quite time consuming. Other
methods for hand detection use the human graph structure as spatial context. But, they
need the visibility of most parts of human [6, 7].
Fig. 1. Overall network structure
Hand Detection Based on Multi-scale Fully Convolutional Networks
21