

5 Conclusion and Future Works
Based on convolution neural network and cyclic neural network, this paper constructs a
CNN-LSTM, which not only retains the local feature extraction ability of CNN, but
also has the “memory” ability of LSTM. Because the rumors in Weibo have the
characteristics of language exaggeration and obvious sentiment, this paper focuses on
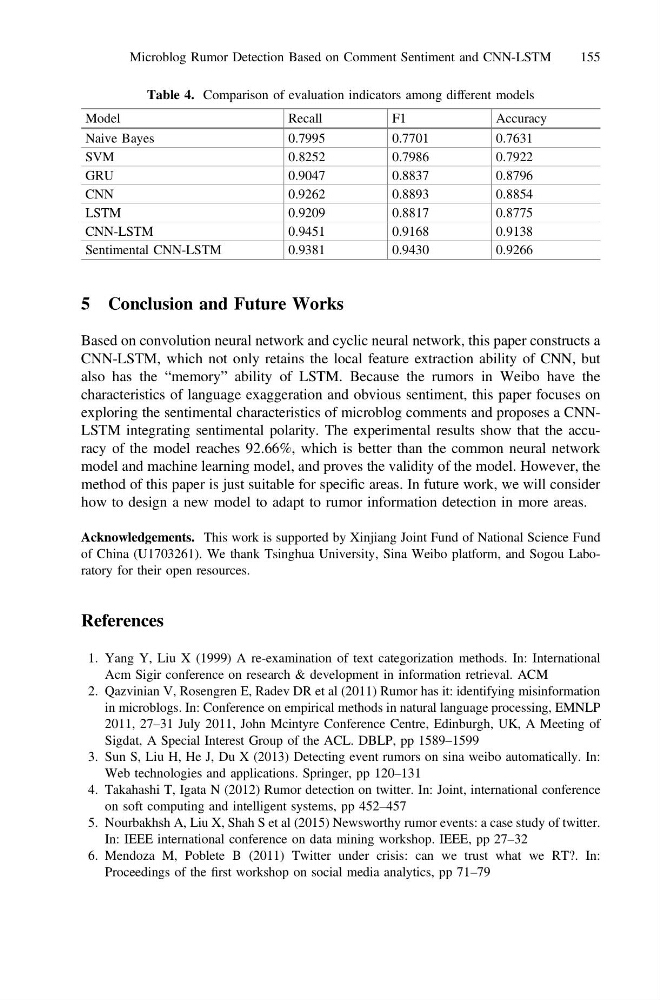
exploring the sentimental characteristics of microblog comments and proposes a CNNLSTM integrating sentimental polarity. The experimental results show that the accuracy of the model reaches 92.66%, which is better than the common neural network
model and machine learning model, and proves the validity of the model. However, the
method of this paper is just suitable for specific areas. In future work, we will consider
how to design a new model to adapt to rumor information detection in more areas.
Acknowledgements. This work is supported by Xinjiang Joint Fund of National Science Fund
of China (U1703261). We thank Tsinghua University, Sina Weibo platform, and Sogou Laboratory for their open resources.
References
1. Yang Y, Liu X (1999) A re-examination of text categorization methods. In: International
Acm Sigir conference on research & development in information retrieval. ACM
2. Qazvinian V, Rosengren E, Radev DR et al (2011) Rumor has it: identifying misinformation
in microblogs. In: Conference on empirical methods in natural language processing, EMNLP
2011, 27–31 July 2011, John Mcintyre Conference Centre, Edinburgh, UK, A Meeting of
Sigdat, A Special Interest Group of the ACL. DBLP, pp 1589–1599
3. Sun S, Liu H, He J, Du X (2013) Detecting event rumors on sina weibo automatically. In:
Web technologies and applications. Springer, pp 120–131
4. Takahashi T, Igata N (2012) Rumor detection on twitter. In: Joint, international conference
on soft computing and intelligent systems, pp 452–457
5. Nourbakhsh A, Liu X, Shah S et al (2015) Newsworthy rumor events: a case study of twitter.
In: IEEE international conference on data mining workshop. IEEE, pp 27–32
6. Mendoza M, Poblete B (2011) Twitter under crisis: can we trust what we RT?. In:
Proceedings of the first workshop on social media analytics, pp 71–79
Table 4. Comparison of evaluation indicators among different models
Model
Recall
F1
Accuracy
Naive Bayes
0.7995
0.7701
0.7631
SVM
0.8252
0.7986
0.7922
GRU
0.9047
0.8837
0.8796
CNN
0.9262
0.8893
0.8854
LSTM
0.9209
0.8817
0.8775
CNN-LSTM
0.9451
0.9168
0.9138
Sentimental CNN-LSTM
0.9381
0.9430
0.9266
Microblog Rumor Detection Based on Comment Sentiment and CNN-LSTM
155