

324
N. Balac
Task Tracker
Task Tracker
Task Tracker
Job Tracker
Name Node
Data Node
Data Node
Data Node
MapReduce
HDFS
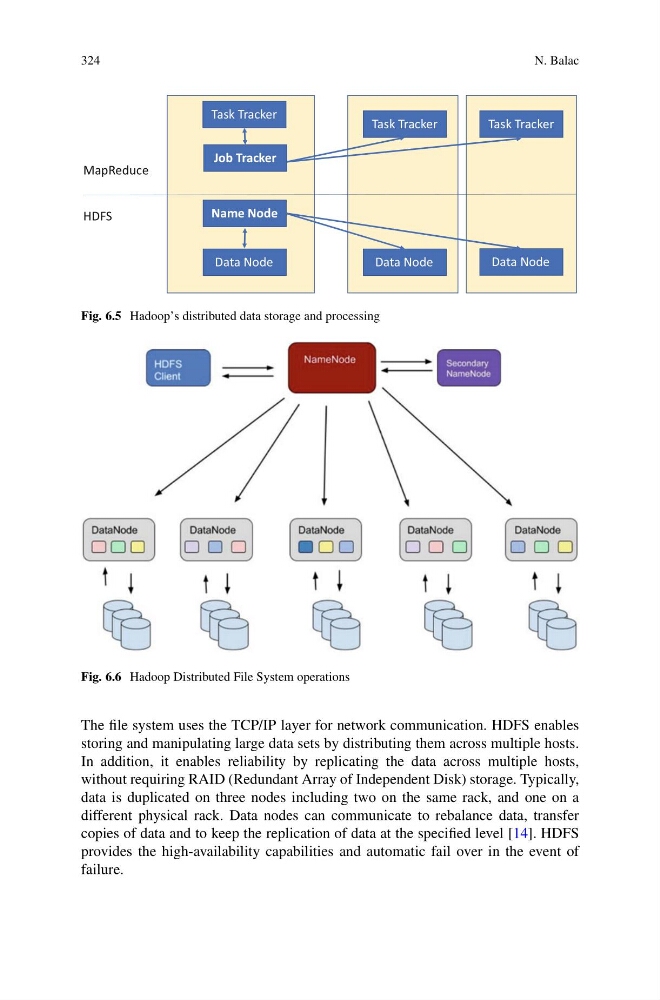
Fig. 6.5 Hadoop’s distributed data storage and processing
Fig. 6.6 Hadoop Distributed File System operations
The file system uses the TCP/IP layer for network communication. HDFS enables
storing and manipulating large data sets by distributing them across multiple hosts.
In addition, it enables reliability by replicating the data across multiple hosts,
without requiring RAID (Redundant Array of Independent Disk) storage. Typically,
data is duplicated on three nodes including two on the same rack, and one on a
different physical rack. Data nodes can communicate to rebalance data, transfer
copies of data and to keep the replication of data at the specified level [14]. HDFS
provides the high-availability capabilities and automatic fail over in the event of
failure.