

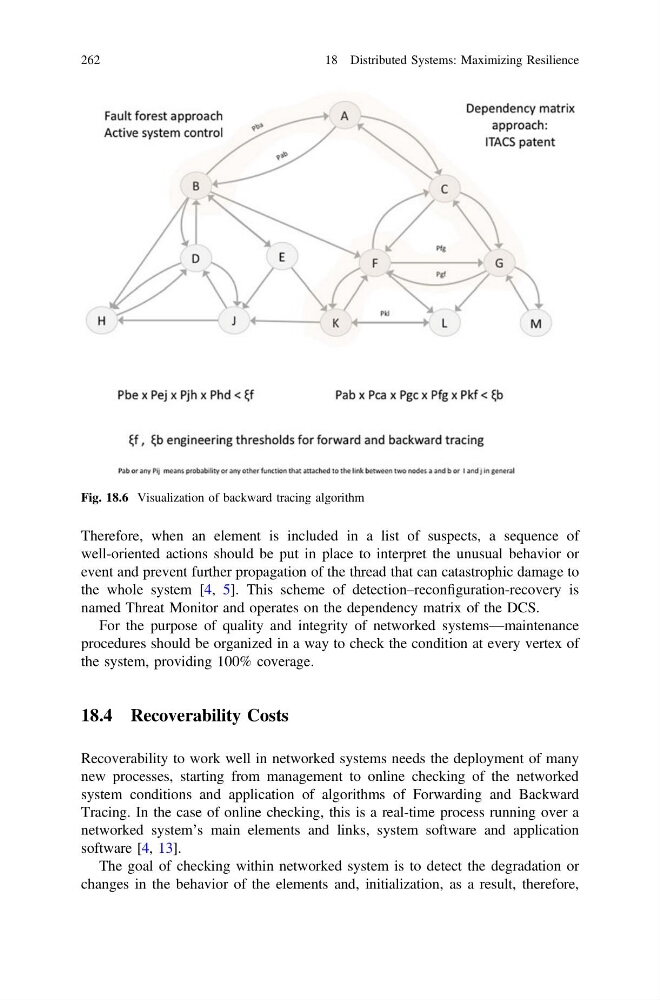
Therefore, when an element is included in a list of suspects, a sequence of
well-oriented actions should be put in place to interpret the unusual behavior or
event and prevent further propagation of the thread that can catastrophic damage to
the whole system [4, 5]. This scheme of detection–reconfiguration-recovery is
named Threat Monitor and operates on the dependency matrix of the DCS.
For the purpose of quality and integrity of networked systems—maintenance
procedures should be organized in a way to check the condition at every vertex of
the system, providing 100% coverage.
18.4 Recoverability Costs
Recoverability to work well in networked systems needs the deployment of many
new processes, starting from management to online checking of the networked
system conditions and application of algorithms of Forwarding and Backward
Tracing. In the case of online checking, this is a real-time process running over a
networked system’s main elements and links, system software and application
software [4, 13].
The goal of checking within networked system is to detect the degradation or
changes in the behavior of the elements and, initialization, as a result, therefore,
Fig. 18.6 Visualization of backward tracing algorithm
262
18 Distributed Systems: Maximizing Resilience