

HDFS major components:
(i) Namenode
Namenode stores the metadata about the file. It has the complete view of the
distributed file system. It tracks which datanode is active and which are node.
In case of any datanode failure, it initiates the operation regarding maintaining
the replication factor by copying the data stored the failed nodes to the active
datanodes. In case, namenode fails, the complete HDFS file system gets
crashed.
(ii) Datanode
It stores the actual data. It performs the read and write operation once it
receives the command from the namenode. It is responsible for block creation,
deletion, and replication. It periodically sends the heartbeat signal to the
namenode.
II. Map Reduce
Hadoop MapReduce is the programming framework. It is one of the major parts
of the Apache Hadoop project. It provides the programing model for data parallel
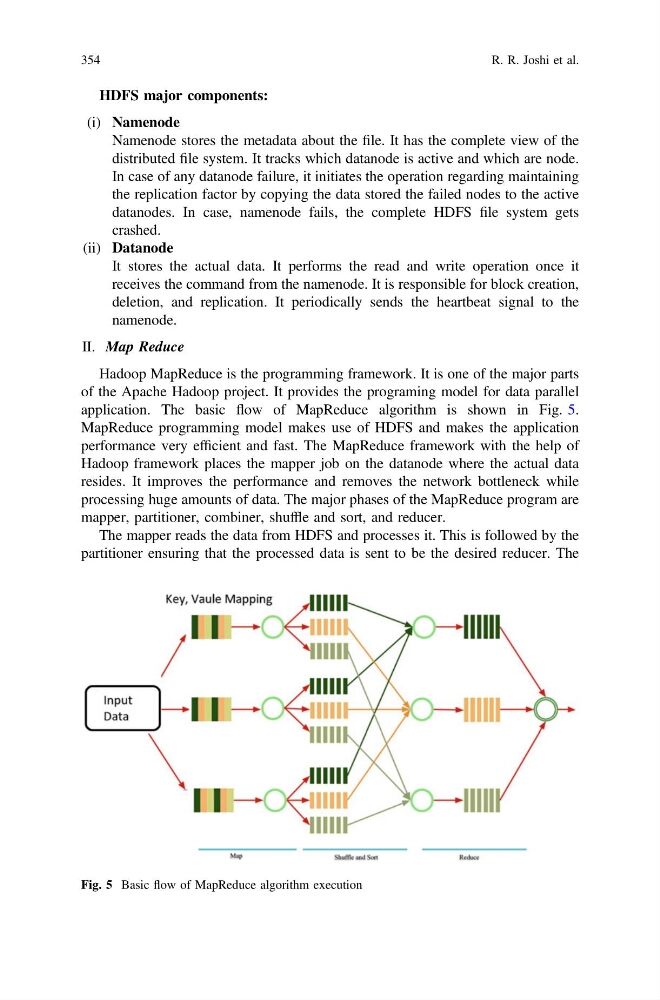
application. The basic flow of MapReduce algorithm is shown in Fig. 5.
MapReduce programming model makes use of HDFS and makes the application
performance very efficient and fast. The MapReduce framework with the help of
Hadoop framework places the mapper job on the datanode where the actual data
resides. It improves the performance and removes the network bottleneck while
processing huge amounts of data. The major phases of the MapReduce program are
mapper, partitioner, combiner, shuffle and sort, and reducer.
The mapper reads the data from HDFS and processes it. This is followed by the
partitioner ensuring that the processed data is sent to be the desired reducer. The
Fig. 5 Basic flow of MapReduce algorithm execution
354
R. R. Joshi et al.