

Hybrid-View Programming of Nuclear Fusion Simulation Code in XcalableMP
199
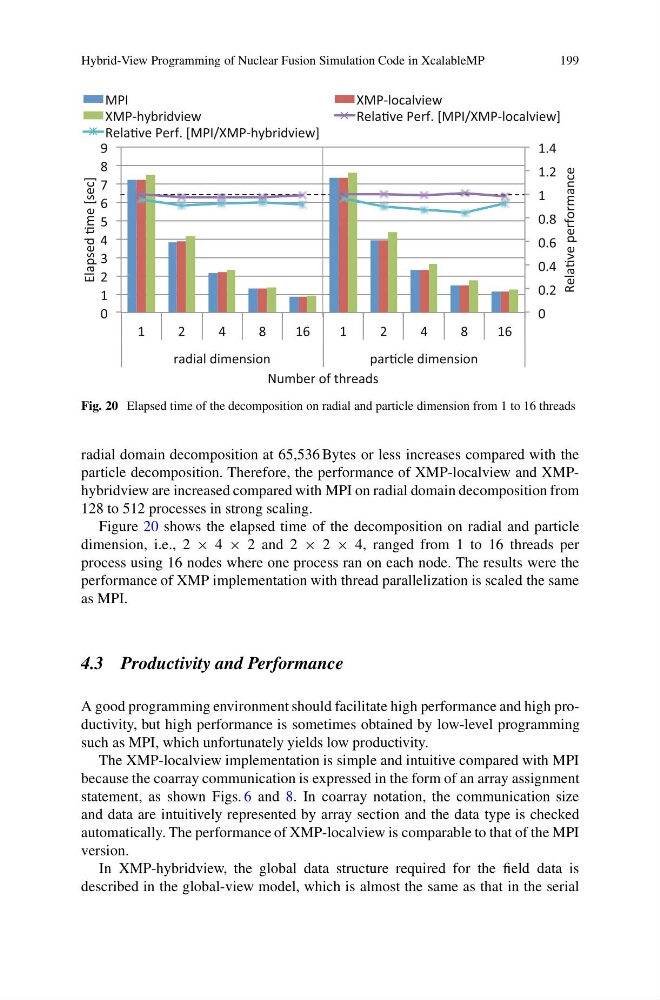
Fig. 20 Elapsed time of the decomposition on radial and particle dimension from 1 to 16 threads
radial domain decomposition at 65,536 Bytes or less increases compared with the
particle decomposition. Therefore, the performance of XMP-localview and XMPhybridview are increased compared with MPI on radial domain decomposition from
128 to 512 processes in strong scaling.
Figure 20 shows the elapsed time of the decomposition on radial and particle
dimension, i.e., 2 × 4 × 2 and 2 × 2 × 4, ranged from 1 to 16 threads per
process using 16 nodes where one process ran on each node. The results were the
performance of XMP implementation with thread parallelization is scaled the same
as MPI.
4.3 Productivity and Performance
A good programming environment should facilitate high performance and high productivity, but high performance is sometimes obtained by low-level programming
such as MPI, which unfortunately yields low productivity.
The XMP-localview implementation is simple and intuitive compared with MPI
because the coarray communication is expressed in the form of an array assignment
statement, as shown Figs. 6 and 8. In coarray notation, the communication size
and data are intuitively represented by array section and the data type is checked
automatically. The performance of XMP-localview is comparable to that of the MPI
version.
In XMP-hybridview, the global data structure required for the field data is
described in the global-view model, which is almost the same as that in the serial