

Hybrid-View Programming of Nuclear Fusion Simulation Code in XcalableMP
191
4 Performance Evaluation
4.1 Experimental Setting
We evaluated the performance of our two implementations using a massively parallel GPU cluster: HA-PACS[1] at the Center for Computational Sciences, University
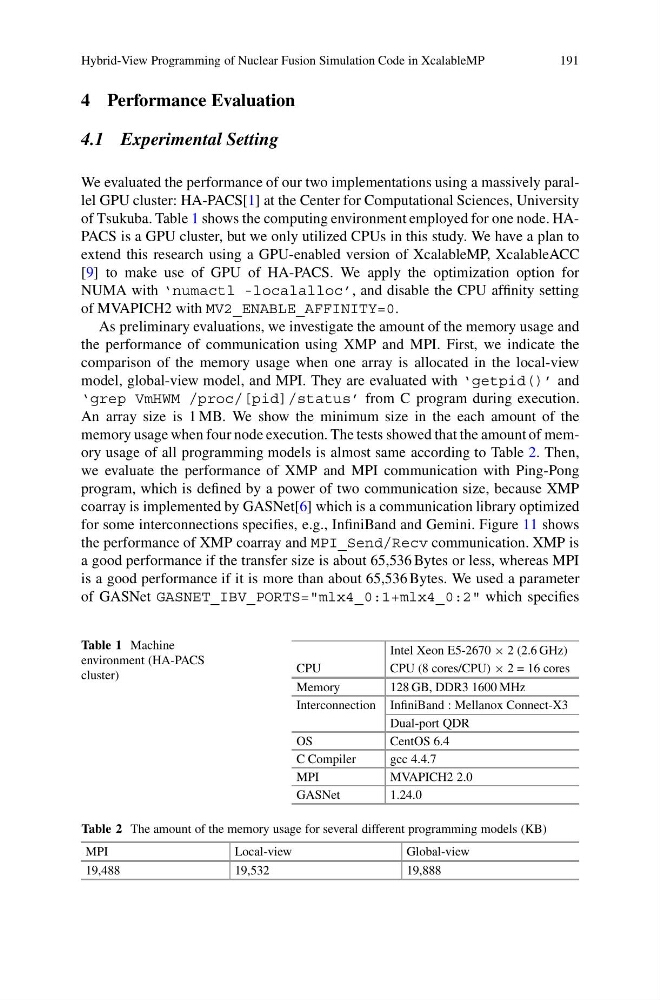
of Tsukuba. Table 1 shows the computing environment employed for one node. HAPACS is a GPU cluster, but we only utilized CPUs in this study. We have a plan to
extend this research using a GPU-enabled version of XcalableMP, XcalableACC
[9] to make use of GPU of HA-PACS. We apply the optimization option for
NUMA with ‘numactl -localalloc’, and disable the CPU affinity setting
of MVAPICH2 with MV2_ENABLE_AFFINITY=0.
As preliminary evaluations, we investigate the amount of the memory usage and
the performance of communication using XMP and MPI. First, we indicate the
comparison of the memory usage when one array is allocated in the local-view
model, global-view model, and MPI. They are evaluated with ‘getpid()’ and
‘grep VmHWM /proc/[pid]/status’ from C program during execution.
An array size is 1 MB. We show the minimum size in the each amount of the
memory usage when four node execution. The tests showed that the amount of memory usage of all programming models is almost same according to Table 2. Then,
we evaluate the performance of XMP and MPI communication with Ping-Pong
program, which is defined by a power of two communication size, because XMP
coarray is implemented by GASNet[6] which is a communication library optimized
for some interconnections specifies, e.g., InfiniBand and Gemini. Figure 11 shows
the performance of XMP coarray and MPI_Send/Recv communication. XMP is
a good performance if the transfer size is about 65,536 Bytes or less, whereas MPI
is a good performance if it is more than about 65,536 Bytes. We used a parameter
of GASNet GASNET_IBV_PORTS="mlx4_0:1+mlx4_0:2" which specifies
Table 1 Machine
environment (HA-PACS
cluster)
Intel Xeon E5-2670 × 2 (2.6 GHz)
CPU
CPU (8 cores/CPU) × 2 = 16 cores
Memory
128 GB, DDR3 1600 MHz
Interconnection InfiniBand : Mellanox Connect-X3
Dual-port QDR
OS
CentOS 6.4
C Compiler
gcc 4.4.7
MPI
MVAPICH2 2.0
GASNet
1.24.0
Table 2 The amount of the memory usage for several different programming models (KB)
MPI
Local-view
Global-view
19,488
19,532
19,888