

XcalableACC: An Integration of XcalableMP and OpenACC
141
1.50
1.25
1.00
0.75
0.50
0.25
0.00
Performance ratio for XcalableACC
18
15
12
9
6
3
0
Time per CG solve (msec.)
MPI+CUDA
MPI+OpenACC
XcalableACC
MPI+CUDA ratio
MPI+OpenACC ratio
2x1 2x2 4x2 4x4 8x4 8x8 16x8 16x16
Number of nodes (NODE_T x NODE_Z)
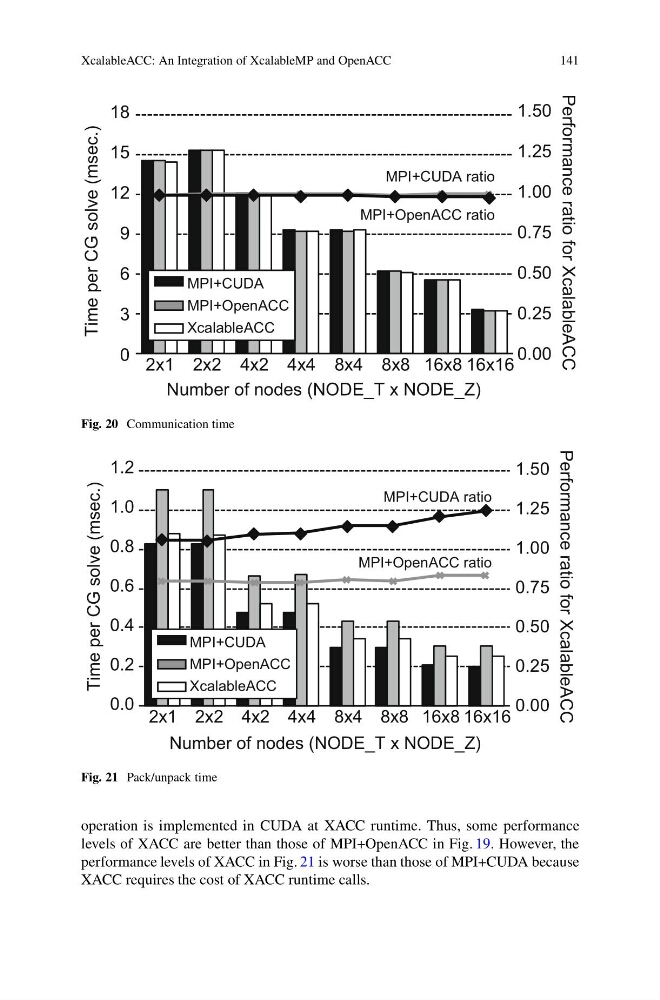
Fig. 20 Communication time
MPI+CUDA ratio
MPI+OpenACC ratio
1.50
1.25
1.00
0.75
0.50
0.25
0.00
Performance ratio for XcalableACC
1.2
1.0
0.8
0.6
0.4
0.2
0.0
Time per CG solve (msec.)
2x1 2x2 4x2 4x4 8x4 8x8 16x8 16x16
Number of nodes (NODE_T x NODE_Z)
MPI+CUDA
MPI+OpenACC
XcalableACC
Fig. 21 Pack/unpack time
operation is implemented in CUDA at XACC runtime. Thus, some performance
levels of XACC are better than those of MPI+OpenACC in Fig. 19. However, the
performance levels of XACC in Fig. 21 is worse than those of MPI+CUDA because
XACC requires the cost of XACC runtime calls.