

15 Statistical Issues in Particle Physics
653
a discontinuous function of μ, and varies from 100% at μ = 0 down to 30% at
μ ≈ 0.5. 8
15.2.2 Unbinned Maximum Likelihood and Goodness of Fit
With sparse data, the unbinned likelihood method is a good one for estimating
parameters of a model. In order to understand whether these estimates of the
parameters are meaningful, we need to know whether the model provides an
adequate description of the data. Unfortunately, as emphasised by Heinrich[33],
the magnitude of the unbinned maximum likelihood is often independent of
whether or not the data agree with the model. He illustrates this by the example
of the determination of the lifetime τ of a particle whose decay distribution is
(1/τ ) exp(−t/τ ). For a set of observed times t i , the maximum likelihood L max
depends on the data t i only through their average value ¯
t. Thus any data distributions
with the same ¯
t would give identical L max , which demonstrates that, at least in this
case, L max gives no discrimination about whether the data are consistent with the
expected distribution.
Another example is fitting an expected distribution (1 + α cos 2 θ)/(1 + α/3)
to data θ i on the decay angle of some particle, to determine α. According to
the expected functional form, the data should be symmetrically distributed about
cos θ = 0. However, the likelihood depends only on the square of cos θ , and
so would be insensitive to all the data having cos θ i negative; this would be very
inconsistent with the expected symmetric distribution.
In contrast Baker and Cousins[34] provide a likelihood method of measuring
goodness of fit for a data histogram compared to a theory. The Poisson likelihood
P P ois (n|μ) for each bin is compared with that for the best possible predicted value
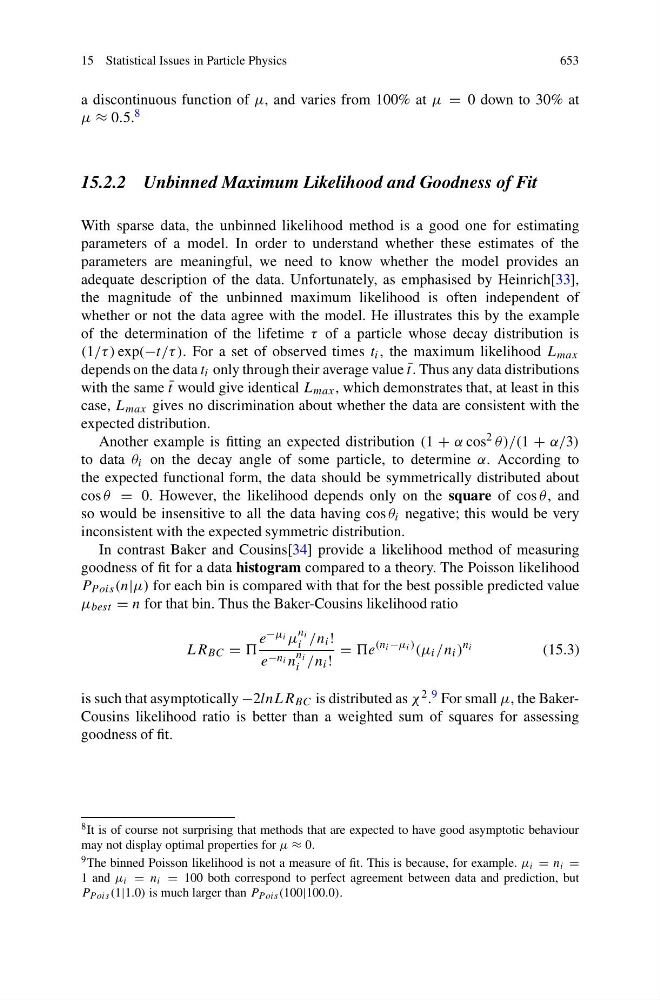
μ best = n for that bin. Thus the Baker-Cousins likelihood ratio
LR BC =
e −μ i μ
n i
i /n i !
e −n i n
n i
i /n i !
= e
(n i −μ i ) (μ i /n i )
n i
(15.3)
is such that asymptotically −2lnLR BC is distributed as χ 2 . 9 For small μ, the BakerCousins likelihood ratio is better than a weighted sum of squares for assessing
goodness of fit.
8 It is of course not surprising that methods that are expected to have good asymptotic behaviour
may not display optimal properties for μ ≈ 0.
9 The binned Poisson likelihood is not a measure of fit. This is because, for example. μ i = n i =
1 and μ i = n i = 100 both correspond to perfect agreement between data and prediction, but
P P ois (1|1.0) is much larger than P P ois (100|100.0).