

350
M. C. Ridley
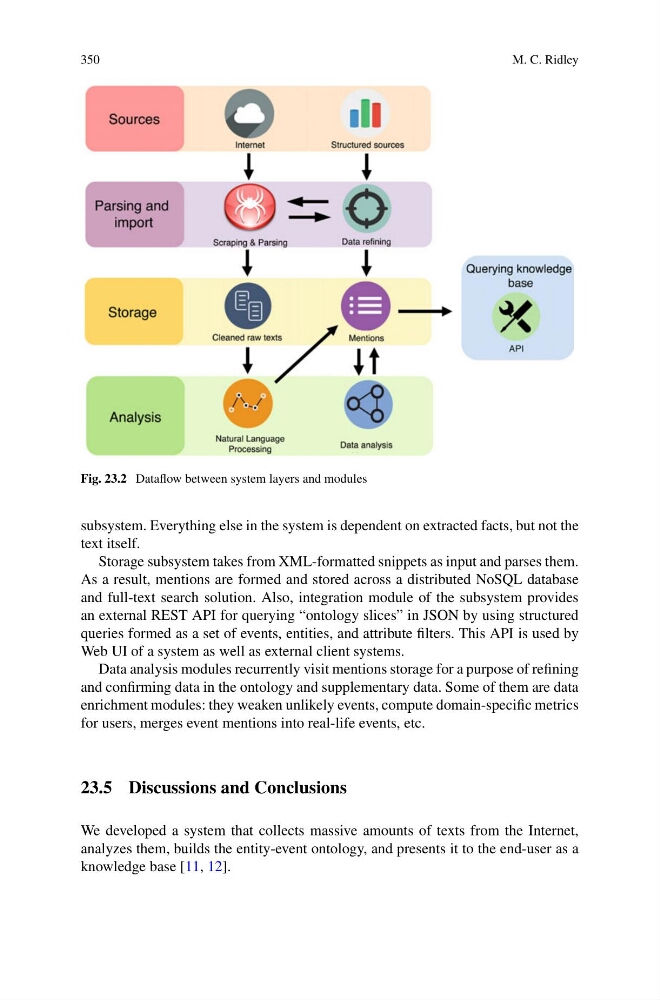
Fig. 23.2 Dataflow between system layers and modules
subsystem. Everything else in the system is dependent on extracted facts, but not the
text itself.
Storage subsystem takes from XML-formatted snippets as input and parses them.
As a result, mentions are formed and stored across a distributed NoSQL database
and full-text search solution. Also, integration module of the subsystem provides
an external REST API for querying “ontology slices” in JSON by using structured
queries formed as a set of events, entities, and attribute filters. This API is used by
Web UI of a system as well as external client systems.
Data analysis modules recurrently visit mentions storage for a purpose of refining
and confirming data in the ontology and supplementary data. Some of them are data
enrichment modules: they weaken unlikely events, compute domain-specific metrics
for users, merges event mentions into real-life events, etc.
23.5 Discussions and Conclusions
We developed a system that collects massive amounts of texts from the Internet,
analyzes them, builds the entity-event ontology, and presents it to the end-user as a
knowledge base [11, 12].