

How to Reduce Computation Time
71
this search process is costly in terms of computation time as it needs to simulate
several value iterations [13] in each state to find the correct solution.
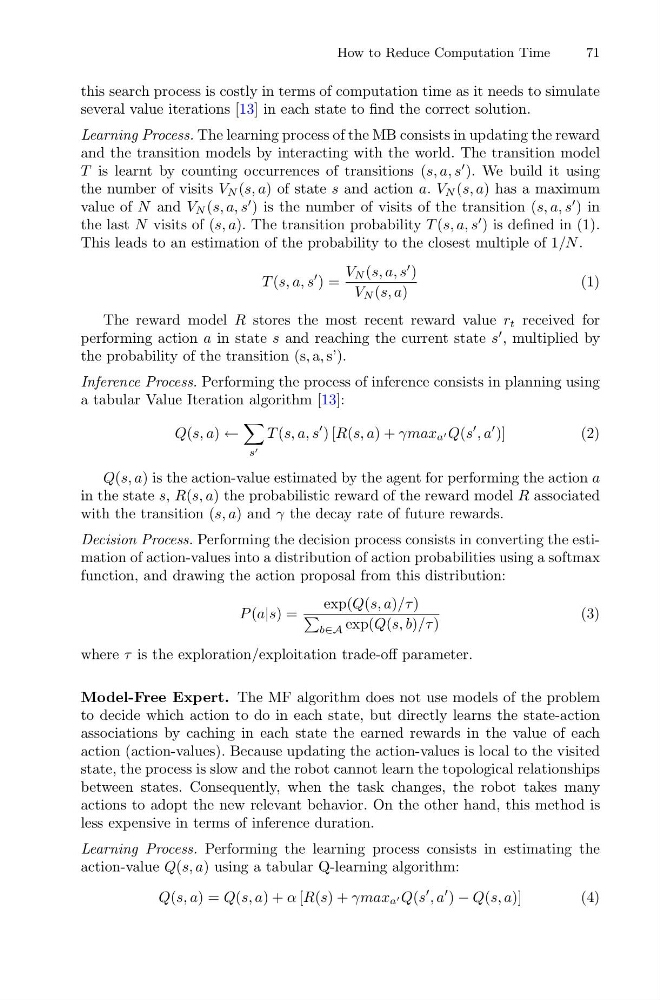
Learning Process. The learning process of the MB consists in updating the reward
and the transition models by interacting with the world. The transition model
T is learnt by counting occurrences of transitions (s, a, s
). We build it using
the number of visits V N (s, a) of state s and action a. V N (s, a) has a maximum
value of N and V N (s, a, s
) is the number of visits of the transition (s, a, s
) in
the last N visits of (s, a). The transition probability T (s, a, s
) is defined in (1).
This leads to an estimation of the probability to the closest multiple of 1/N .
T (s, a, s
) =
V N (s, a, s
)
V N (s, a)
(1)
The reward model R stores the most recent reward value r t received for
performing action a in state s and reaching the current state s
, multiplied by
the probability of the transition (s, a, s’).
Inference Process. Performing the process of inference consists in planning using
a tabular Value Iteration algorithm [13]:
Q(s, a) ←
s
T (s, a, s
) [R(s, a) + γmax a Q(s
, a
)]
(2)
Q(s, a) is the action-value estimated by the agent for performing the action a
in the state s, R(s, a) the probabilistic reward of the reward model R associated
with the transition (s, a) and γ the decay rate of future rewards.
Decision Process. Performing the decision process consists in converting the estimation of action-values into a distribution of action probabilities using a softmax
function, and drawing the action proposal from this distribution:
P (a|s) =
exp(Q(s, a)/τ )
b∈A exp(Q(s, b)/τ )
(3)
where τ is the exploration/exploitation trade-off parameter.
Model-Free Expert. The MF algorithm does not use models of the problem
to decide which action to do in each state, but directly learns the state-action
associations by caching in each state the earned rewards in the value of each
action (action-values). Because updating the action-values is local to the visited
state, the process is slow and the robot cannot learn the topological relationships
between states. Consequently, when the task changes, the robot takes many
actions to adopt the new relevant behavior. On the other hand, this method is
less expensive in terms of inference duration.
Learning Process. Performing the learning process consists in estimating the
action-value Q(s, a) using a tabular Q-learning algorithm:
Q(s, a) = Q(s, a) + α [R(s) + γmax a Q(s
, a
) − Q(s, a)]
(4)