

1 Coalescent Models
17
π, is found by comparing each sampled sequence with every other, counting the
number of differences between them, and taking the average over all pairs. The site
frequencies, ξ i , are obtained by counting the number of SNPs in the data at which
the mutant base is found in i copies in the sample, for i from 1 to n − 1. The ancestral
state at each SNP is generally ascertained as the state in a sequence from a closely
related species. If this information is not available or is unreliable, site frequencies
just count the less frequent base, so that 1 ≤ i ≤ n/2.
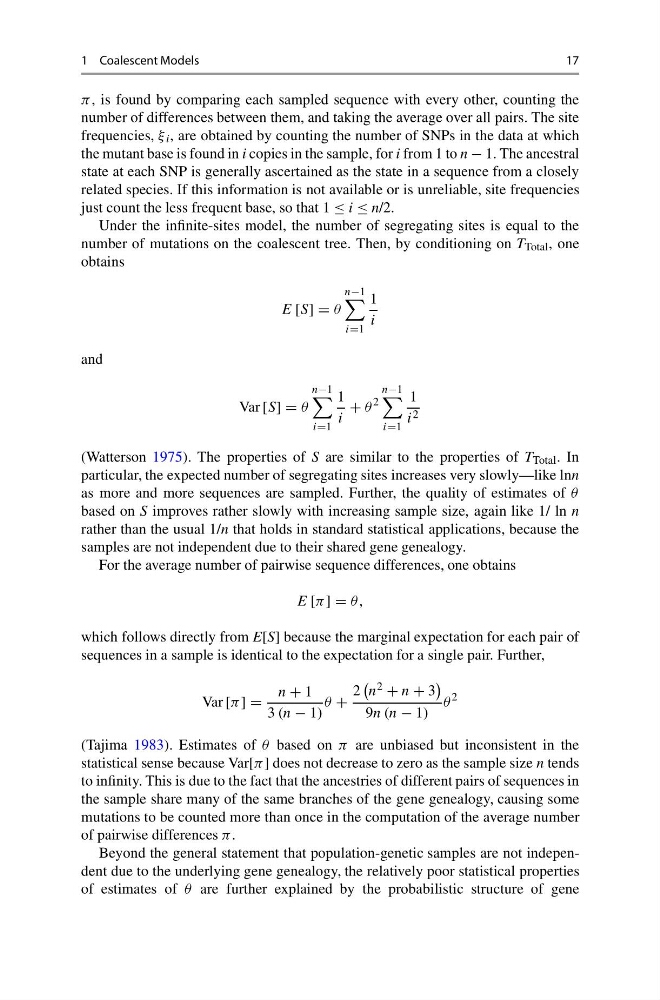
Under the infinite-sites model, the number of segregating sites is equal to the
number of mutations on the coalescent tree. Then, by conditioning on T Total , one
obtains
E [S] = θ
n−1
i=1
1
i
and
Var [S] = θ
n−1
i=1
1
i
+ θ
2
n−1
i=1
1
i 2
(Watterson 1975). The properties of S are similar to the properties of T Total . In
particular, the expected number of segregating sites increases very slowly—like lnn
as more and more sequences are sampled. Further, the quality of estimates of θ
based on S improves rather slowly with increasing sample size, again like 1/ ln n
rather than the usual 1/n that holds in standard statistical applications, because the
samples are not independent due to their shared gene genealogy.
For the average number of pairwise sequence differences, one obtains
E [π] = θ,
which follows directly from E[S] because the marginal expectation for each pair of
sequences in a sample is identical to the expectation for a single pair. Further,
Var [π] =
n + 1
3 (n − 1)
θ +
2
n 2 + n + 3
9n (n − 1)
θ
2
(Tajima 1983). Estimates of θ based on π are unbiased but inconsistent in the
statistical sense because Var[π] does not decrease to zero as the sample size n tends
to infinity. This is due to the fact that the ancestries of different pairs of sequences in
the sample share many of the same branches of the gene genealogy, causing some
mutations to be counted more than once in the computation of the average number
of pairwise differences π.
Beyond the general statement that population-genetic samples are not independent due to the underlying gene genealogy, the relatively poor statistical properties
of estimates of θ are further explained by the probabilistic structure of gene