

1 Coalescent Models
15
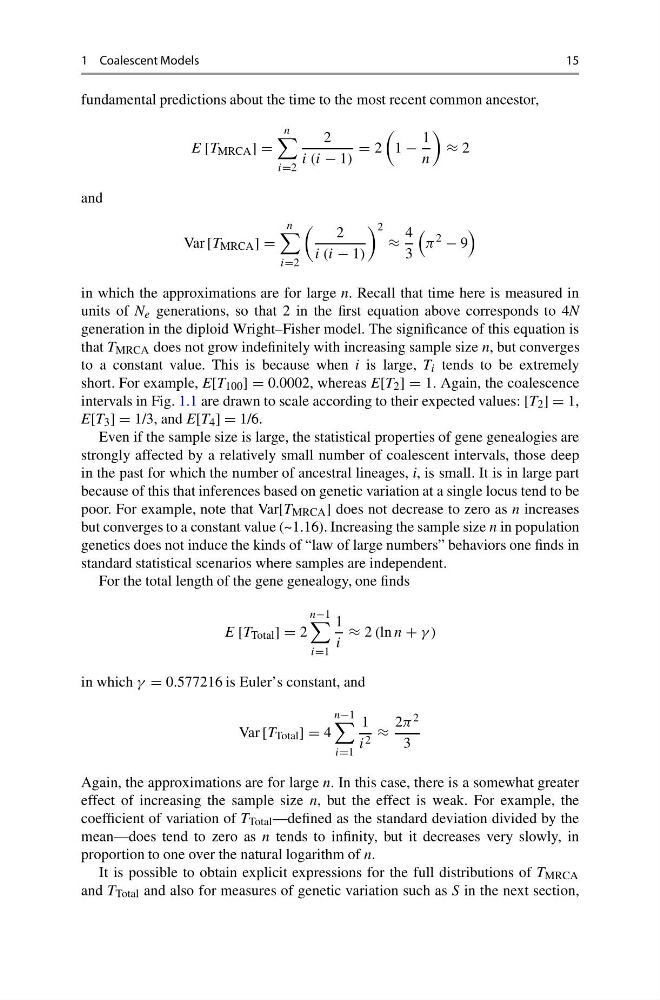
fundamental predictions about the time to the most recent common ancestor,
E [T MRCA ] =
n
i=2
2
i (i − 1)
= 2
1 −
1
n
≈ 2
and
Var [T MRCA ] =
n
i=2
2
i (i − 1)
2
≈
4
3
π
2
− 9
in which the approximations are for large n. Recall that time here is measured in
units of N e generations, so that 2 in the first equation above corresponds to 4N
generation in the diploid Wright–Fisher model. The significance of this equation is
that T MRCA does not grow indefinitely with increasing sample size n, but converges
to a constant value. This is because when i is large, T i tends to be extremely
short. For example, E[T 100 ] = 0.0002, whereas E[T 2 ] = 1. Again, the coalescence
intervals in Fig. 1.1 are drawn to scale according to their expected values: [T 2 ] = 1,
E[T 3 ] = 1/3, and E[T 4 ] = 1/6.
Even if the sample size is large, the statistical properties of gene genealogies are
strongly affected by a relatively small number of coalescent intervals, those deep
in the past for which the number of ancestral lineages, i, is small. It is in large part
because of this that inferences based on genetic variation at a single locus tend to be
poor. For example, note that Var[T MRCA ] does not decrease to zero as n increases
but converges to a constant value (~1.16). Increasing the sample size n in population
genetics does not induce the kinds of “law of large numbers” behaviors one finds in
standard statistical scenarios where samples are independent.
For the total length of the gene genealogy, one finds
E [T Total ] = 2
n−1
i=1
1
i
≈ 2 (ln n + γ )
in which γ = 0.577216 is Euler’s constant, and
Var [T Total ] = 4
n−1
i=1
1
i 2 ≈
2π 2
3
Again, the approximations are for large n. In this case, there is a somewhat greater
effect of increasing the sample size n, but the effect is weak. For example, the
coefficient of variation of T Total —defined as the standard deviation divided by the
mean—does tend to zero as n tends to infinity, but it decreases very slowly, in
proportion to one over the natural logarithm of n.
It is possible to obtain explicit expressions for the full distributions of T MRCA
and T Total and also for measures of genetic variation such as S in the next section,