

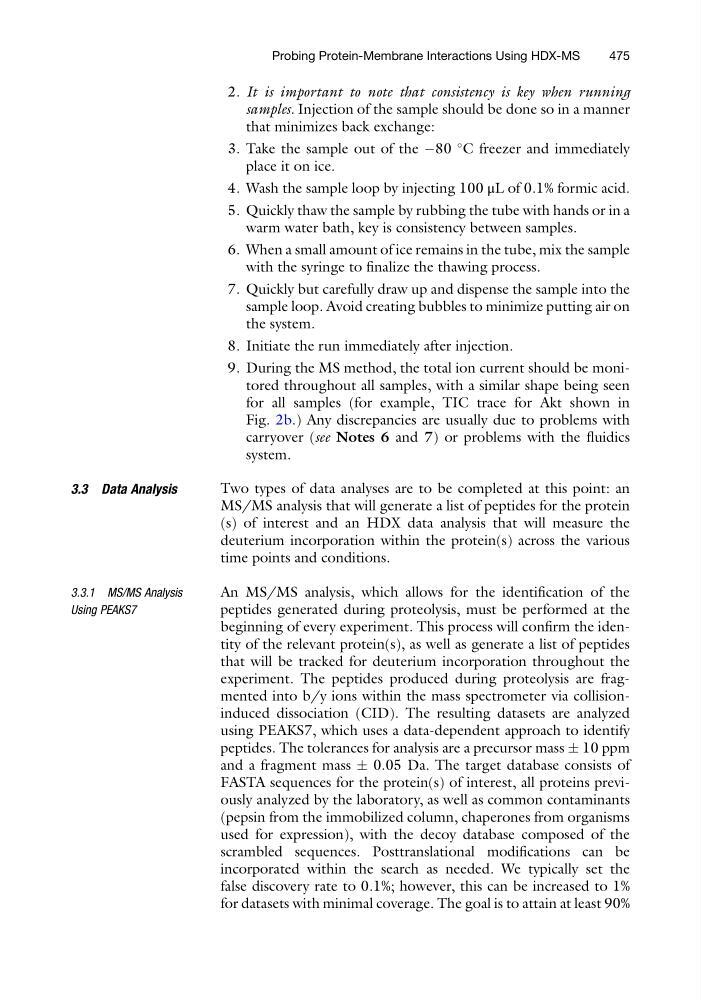
2. It is important to note that consistency is key when running
samples. Injection of the sample should be done so in a manner
that minimizes back exchange:
3. Take the sample out of the À80
C freezer and immediately
place it on ice.
4. Wash the sample loop by injecting 100 μL of 0.1% formic acid.
5. Quickly thaw the sample by rubbing the tube with hands or in a
warm water bath, key is consistency between samples.
6. When a small amount of ice remains in the tube, mix the sample
with the syringe to finalize the thawing process.
7. Quickly but carefully draw up and dispense the sample into the
sample loop. Avoid creating bubbles to minimize putting air on
the system.
8. Initiate the run immediately after injection.
9. During the MS method, the total ion current should be monitored throughout all samples, with a similar shape being seen
for all samples (for example, TIC trace for Akt shown in
Fig. 2b.) Any discrepancies are usually due to problems with
carryover (see Notes 6 and 7) or problems with the fluidics
system.
3.3 Data Analysis
Two types of data analyses are to be completed at this point: an
MS/MS analysis that will generate a list of peptides for the protein
(s) of interest and an HDX data analysis that will measure the
deuterium incorporation within the protein(s) across the various
time points and conditions.
3.3.1 MS/MS Analysis
Using PEAKS7
An MS/MS analysis, which allows for the identification of the
peptides generated during proteolysis, must be performed at the
beginning of every experiment. This process will confirm the identity of the relevant protein(s), as well as generate a list of peptides
that will be tracked for deuterium incorporation throughout the
experiment. The peptides produced during proteolysis are fragmented into b/y ions within the mass spectrometer via collisioninduced dissociation (CID). The resulting datasets are analyzed
using PEAKS7, which uses a data-dependent approach to identify
peptides. The tolerances for analysis are a precursor mass Æ 10 ppm
and a fragment mass Æ 0.05 Da. The target database consists of
FASTA sequences for the protein(s) of interest, all proteins previously analyzed by the laboratory, as well as common contaminants
(pepsin from the immobilized column, chaperones from organisms
used for expression), with the decoy database composed of the
scrambled sequences. Posttranslational modifications can be
incorporated within the search as needed. We typically set the
false discovery rate to 0.1%; however, this can be increased to 1%
for datasets with minimal coverage. The goal is to attain at least 90%
Probing Protein-Membrane Interactions Using HDX-MS
475