

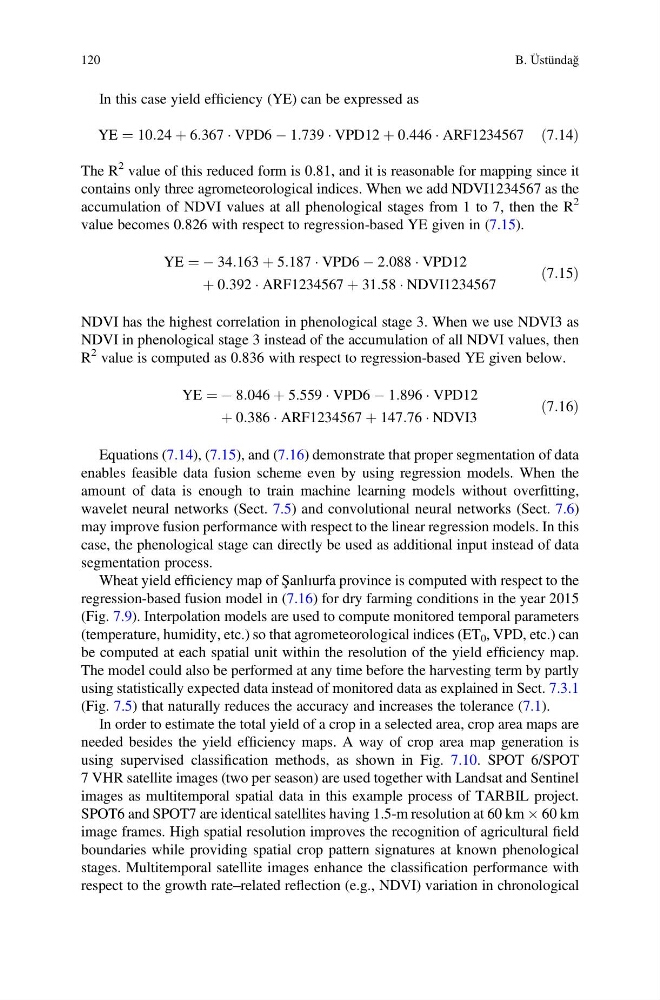
In this case yield efficiency (YE) can be expressed as
YE ¼ 10:24 þ 6:367 Á VPD6 À 1:739 Á VPD12 þ 0:446 Á ARF1234567 ð7:14Þ
The R
2 value of this reduced form is 0.81, and it is reasonable for mapping since it
contains only three agrometeorological indices. When we add NDVI1234567 as the
accumulation of NDVI values at all phenological stages from 1 to 7, then the R
2
value becomes 0.826 with respect to regression-based YE given in (7.15).
YE ¼ À 34:163 þ 5:187 Á VPD6 À 2:088 Á VPD12
þ 0:392 Á ARF1234567 þ 31:58 Á NDVI1234567
ð7:15Þ
NDVI has the highest correlation in phenological stage 3. When we use NDVI3 as
NDVI in phenological stage 3 instead of the accumulation of all NDVI values, then
R
2 value is computed as 0.836 with respect to regression-based YE given below.
YE ¼ À 8:046 þ 5:559 Á VPD6 À 1:896 Á VPD12
þ 0:386 Á ARF1234567 þ 147:76 Á NDVI3
ð7:16Þ
Equations (7.14), (7.15), and (7.16) demonstrate that proper segmentation of data
enables feasible data fusion scheme even by using regression models. When the
amount of data is enough to train machine learning models without overfitting,
wavelet neural networks (Sect. 7.5) and convolutional neural networks (Sect. 7.6)
may improve fusion performance with respect to the linear regression models. In this
case, the phenological stage can directly be used as additional input instead of data
segmentation process.
Wheat yield efficiency map of Şanlıurfa province is computed with respect to the
regression-based fusion model in (7.16) for dry farming conditions in the year 2015
(Fig. 7.9). Interpolation models are used to compute monitored temporal parameters
(temperature, humidity, etc.) so that agrometeorological indices (ET 0 , VPD, etc.) can
be computed at each spatial unit within the resolution of the yield efficiency map.
The model could also be performed at any time before the harvesting term by partly
using statistically expected data instead of monitored data as explained in Sect. 7.3.1
(Fig. 7.5) that naturally reduces the accuracy and increases the tolerance (7.1).
In order to estimate the total yield of a crop in a selected area, crop area maps are
needed besides the yield efficiency maps. A way of crop area map generation is
using supervised classification methods, as shown in Fig. 7.10. SPOT 6/SPOT
7 VHR satellite images (two per season) are used together with Landsat and Sentinel
images as multitemporal spatial data in this example process of TARBIL project.
SPOT6 and SPOT7 are identical satellites having 1.5-m resolution at 60 km  60 km
image frames. High spatial resolution improves the recognition of agricultural field
boundaries while providing spatial crop pattern signatures at known phenological
stages. Multitemporal satellite images enhance the classification performance with
respect to the growth rate–related reflection (e.g., NDVI) variation in chronological
120
B. Üstündağ