

in simple and generalized linear models. The versions
of R and INLA used in this simulation study are 4.0
and 20.05.12, respectively.
This paper is organized as follows: the methodology,
which consists of the setup and simulation procedures
for the models under consideration, results and discussion, and finally, the conclusion, limitations, and
recommendations. Emboldened uppercase letters are
matrices and emboldened lowercase letters are vectors. Again, emboldened Greek letters are vectors
of parameters and non-emboldened Greek letters are
parameters.
3 METHODOLOGY
3.1 McMC formulation for the simple linear model
3.1.1 Simple linear model
A model given by
y = X β + ε, ε ∼ N
0, σ
2 I
(1)
is a linear model in X , where X = design matrix, y =
observed data or response vector, β = parameter vector, ε = error vector and I = identity matrix(Bingham,
N. J. & Fry, J. M., 2010). Upon the assumption that
the error vector, ε, is Normally distributed with mean
vector = 0 and a diagonal matrix of σ
2 , the variancecovariance matrix, the only unknown parameters to be
determined in this model are β, and σ
2 .
3.1.2 Setup
Consider the setup for n observations where the
response variable, y i , i = 1, 2, · · · , n, is normally distributed with mean, η i = x
T
i β, and variance, τ
−1 (τ
being the precision parameter with τ
−1
= σ
2 ). With a
flat prior distribution on β and a Gamma prior on τ, say
τ ∼ Gamma(a, b) where a is the shape parameter and
b, the rate parameter, the full conditional distributions
of β and τ can be deduced. To deduce them, the likelihood and the prior distributions had to be defined,
after which the corresponding posterior distribution
was determined and thereafter, the full conditionals
derived. The details are as follows:
The likelihood of y is given p
y|β, τ
−1
=
(2π)
−n/2 τ
n/2 exp
−
τ
2
y − X β
T
y − X β
(2)
The prior distribution of τ is also given by
p (τ) =
b
a
(a)
τ
(a−1) exp (−bτ)
(3)
Lastly, the flat prior distribution of β is given by
p (β) = 1
(4)
The posterior distribution, which is a product of the
likelihood in equation (2), the prior distributions of
equations (3) and (4), is given by
p
β, τ|y
∝ p
y|β, τ
−1
p (β) p (τ)
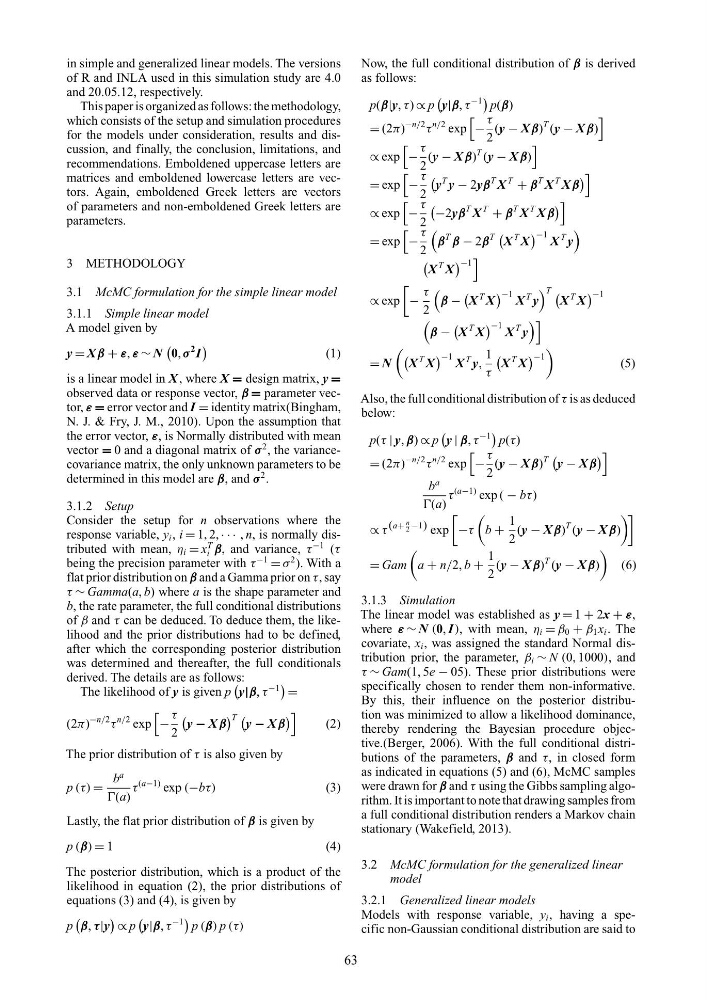
Now, the full conditional distribution of β is derived
as follows:
p(β|y, τ) ∝ p
y|β, τ
−1
p(β)
= (2π)
−n/2 τ
n/2 exp
−
τ
2
(y − X β)
T (y − X β)
∝ exp
−
τ
2
(y − X β)
T (y − X β)
= exp
−
τ
2
y
T y − 2yβ
T X
T + β
T X
T X β
∝ exp
−
τ
2
−2yβ
T X
T + β
T X
T X β
= exp
−
τ
2
β
T β − 2β
T
X
T X
−1 X
T y
X
T X
−1
∝ exp
−
τ
2
β −
X
T X
−1 X
T y
T
X
T X
−1
β −
X
T X
−1 X
T y
= N
X
T X
−1 X
T y,
1
τ
X
T X
−1
(5)
Also, the full conditional distribution of τ is as deduced
below:
p(τ | y, β) ∝ p
y | β, τ
−1
p(τ)
= (2π)
−n/2 τ
n/2 exp
−
τ
2
(y − X β)
T
y − X β
b
a
(a)
τ
(a−1) exp ( − bτ)
∝ τ (a+
n
2 −1) exp
−τ
b +
1
2
(y − X β)
T (y − X β)
= Gam
a + n/2, b +
1
2
(y − X β)
T (y − X β)
(6)
3.1.3 Simulation
The linear model was established as y = 1 + 2x + ε,
where ε ∼ N (0, I ), with mean, η i = β 0 + β 1 x i . The
covariate, x i , was assigned the standard Normal distribution prior, the parameter, β i ∼ N (0, 1000), and
τ ∼ Gam(1, 5e − 05). These prior distributions were
specifically chosen to render them non-informative.
By this, their influence on the posterior distribution was minimized to allow a likelihood dominance,
thereby rendering the Bayesian procedure objective.(Berger, 2006). With the full conditional distributions of the parameters, β and τ, in closed form
as indicated in equations (5) and (6), McMC samples
were drawn for β and τ using the Gibbs sampling algorithm. It is important to note that drawing samples from
a full conditional distribution renders a Markov chain
stationary (Wakefield, 2013).
3.2 McMC formulation for the generalized linear
model
3.2.1 Generalized linear models
Models with response variable, y i , having a specific non-Gaussian conditional distribution are said to
63